
🧠 CodeCortex Context Engine
Open-source context intelligence infrastructure for AI coding agents
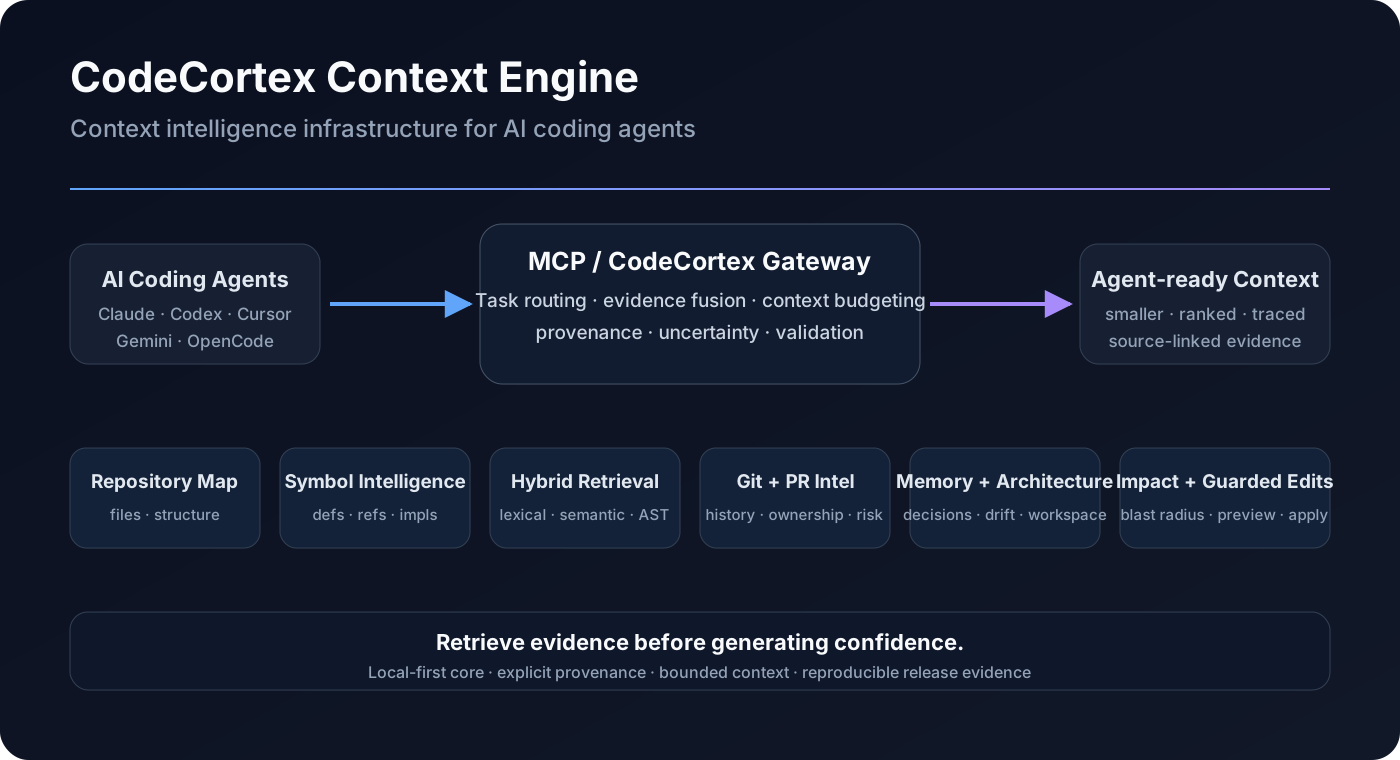
Map the repository · resolve symbols · retrieve task-specific evidence · estimate impact · edit with guardrails
⭐ Star CodeCortex · ❤️ Support Project · Documentation · Latest Release · Contribute
Why CodeCortex?
A coding agent can read code. The harder problem is deciding what matters, what is connected, what can break, and how much context is actually worth sending to the model.
CodeCortex turns a repository into a query-specific evidence system for coding agents:
- Repository + symbol intelligence — structure, definitions, references, dependencies, and call relationships.
- Evidence-aware retrieval — lexical, semantic, structural, graph, Git, architecture, and memory signals are ranked together.
- Impact before edits — reverse dependencies, affected tests, ownership, and change risk are inspectable before mutation.
- Guarded changes — semantic edits and structural rewrite previews keep source boundaries and review steps explicit.
- Persistent project context — architecture, history, project/team memory, traces, and multi-repo workspaces survive beyond one chat.
Core rule: retrieve evidence before generating confidence.
60-second start
Requires Python 3.11–3.13.
python -m pip install --upgrade codecortex-context-engine
cortex init .
cortex index
cortex doctor
Then ask the repository useful questions:
cortex architecture
cortex semantic "authentication and session lifecycle"
cortex impact AuthService
Or expose the repository to an MCP-capable coding agent:
cortex mcp --path .
Works with coding agents
CodeCortex includes merge-safe project configuration for Claude Code, Codex, Cursor, Gemini CLI, and OpenCode.
cortex agents detect
cortex agents configure --dry-run
# or configure every supported target explicitly:
cortex agents configure --all
The configurator only manages CodeCortex-owned MCP entries and keeps user-owned configuration intact.
See it work locally
The repository ships a deterministic demo project and demo runner:
python scripts/demo.py
The demo indexes the fixture repository, analyzes the blast radius of AuthService, routes an evidence request, and reports measured context/trace data. It does not fabricate benchmark values.
Reproducible evidence snapshot
These are committed hardening measurements, not generalized performance promises:
See HARDENING_REPORT.md and benchmarks/ for scope, methodology, limitations, and reproducibility notes.
❤️ Support CodeCortex — If CodeCortex saves you time, consider supporting its continued open-source development. Crypto support →
🇬🇧 English
Give the coding agent a map before asking it to navigate the codebase.
CodeCortex in one sentence
CodeCortex turns a software repository into a query-specific evidence system for AI coding agents.
It sits between an agent and a codebase. It builds durable intelligence about repository structure, symbols, relationships, Git history, ownership, architecture, team decisions, impact, and validation. For each task, it tries to return the smallest useful evidence package instead of forcing the model to reopen broad parts of the repository and reconstruct the same facts again.
CodeCortex is not another general chat UI. It is not a model provider. It does not claim that an agent becomes infallible. It is context infrastructure: a layer that improves what the agent gets to reason with.
Core rule: retrieve evidence before generating confidence.
Why this exists
A strong coding model can read code. The harder engineering problem is deciding what deserves attention, what is connected to it, what changed, what is ambiguous, who owns the area, and what can break after a change.
Without a context engine, the work often looks like this:
CodeCortex changes the stream:
The goal is not more context.
The goal is higher-value evidence per token.
Architecture
Live evidence stream
flowchart LR
    A[AI Coding Agent] --> G[CodeCortex Gateway]
    G --> R[Adaptive Router]

    R --> REP[Repository Intelligence]
    R --> SYM[Symbol Intelligence]
    R --> RET[Hybrid Retrieval]
    R --> GIT[Git + PR Intelligence]
    R --> MEM[Project + Team Memory]
    R --> ARC[Architecture + Drift]
    R --> IMP[Impact + Validation]

    REP --> E[Evidence Surface]
    SYM --> E
    RET --> E
    GIT --> E
    MEM --> E
    ARC --> E
    IMP --> E

    E --> C[Context Pipeline]
    C --> B[Rank + Dedup + Slice + Budget]
    B --> G
    G --> A
The repository remains the source of executable truth. Graphs, memory, semantic retrieval, architecture inference, and summaries help interpretation. They do not replace current source, configuration, and tests.
Current capability map
The CodeCortex Doctrine
These are engineering rules, not marketing slogans.
Doctrine 01 — Evidence before confidence
A resolved symbol, a semantic match, an inferred edge, a memory entry, and a Git observation are different evidence classes. CodeCortex should not flatten them into one certainty level.
Doctrine 02 — Smallest useful context
The best context package is not the largest package that fits. It is the smallest package that contains enough source, relationships, history, and validation evidence to reason about the current task.
Doctrine 03 — Source remains source
Memory can explain intent. Git can explain history. Graphs can explain relationships. Retrieval can suggest relevance. Current source, configuration, tests, and reproducible artifacts remain authoritative for executable behavior.
Doctrine 04 — Uncertainty is information
If two symbols are plausible targets, that ambiguity matters. If architecture is inferred, missing signals matter. If an optional integration cannot run, “unavailable” is more useful than a fabricated success.
Doctrine 05 — Every change has a blast radius
A small diff can be high risk. A large diff can be mechanical. The useful questions are: which symbols changed, who depends on them, which tests exercise them, who owns the area, and what evidence supports the risk.
Doctrine 06 — Local-first is a trust decision
Core repository intelligence works locally. Any network boundary, credential, remote tool, quota, policy, and data transfer must remain explicit.
Doctrine 07 — Reproducibility beats impressive numbers
A benchmark claim without a reproducible specification, pinned revision, environment, measured output, and artifact is not strong evidence.
Doctrine 08 — Scale through explicit coordination
Workers have identity, capability, leases, failure, retry, and state. Shared memory has synchronization and conflict behavior. Remote tools have authentication and policy.
Quick Start
Install
CodeCortex supports Python 3.11, 3.12, and 3.13.
Optional parser support:
Optional local neural semantic embeddings:
Start inside a repository
A 30-second mental model
The agent still reasons. CodeCortex changes what it gets to reason with.
Task streams
Bug investigation
sequenceDiagram
    participant A as Agent
    participant C as CodeCortex
    participant R as Repository
    participant G as Graph
    participant H as Git/History
    participant V as Validation

    A->>C: Trace a failing behavior
    C->>R: locate source and symbols
    C->>G: resolve callers and dependencies
    C->>H: inspect recent change and ownership
    C->>V: identify tests and validation signals
    C-->>A: compact evidence package + impact
A useful investigation should answer:
- Where is the behavior implemented?
- What callers and references participate?
- What changed recently?
- Which alternate path can invalidate the hypothesis?
- Which test would fail if the explanation is wrong?
- What is the smallest safe change?
Pull-request review
PR size is only one signal.
Multi-repository work
The repositories keep their identity. CodeCortex federates evidence instead of pretending they are one physical codebase.
Intelligence surfaces
Incremental indexing turns files and program units into durable repository state. Retrieval, architecture inference, impact analysis, and MCP tools can reuse that state instead of rediscovering the whole repository for every request.
Language-aware parsing extracts program units and keeps container identity where possible. Cross-file resolution intentionally preserves ambiguity and candidate reasons instead of silently choosing a same-name symbol.
Code is not ordinary prose. CodeCortex combines lexical evidence, semantic similarity, symbol metadata, and structural context. Context slicing favors meaningful structural units and bounded windows instead of uncontrolled file dumps.
Current source answers what the code does now. Git explains how it arrived there. History, blame, ownership, churn, and PR analysis add change evidence to the static code model.
Project memory stores reusable facts and decisions. Team memory adds revisions, actor/source metadata, optimistic concurrency, and conflict behavior. Memory can explain “why,” but current source and tests remain authoritative.
Architecture inference returns evidence and confidence. A saved fingerprint can be compared with the current graph so new dependency directions, coupling growth, and structural drift become inspectable.
Impact analysis walks reverse relationships and affected tests. Validation challenges a proposed change against repository evidence. A risk score is useful only when the evidence behind it stays visible.
Guarded editing
Current semantic edit operations include:
The intended change discipline is:
Not:
MCP: one agent-facing surface
The MCP surface exposes repository mapping, symbol search, references, dependency graph inspection, impact analysis, hybrid retrieval, compact context, architecture intelligence, Git history, PR intelligence, memory, workspace search, traces, validation, and statistics.
Distributed operation
flowchart TB
    AG[AI Agents] --> GW[Remote MCP Gateway]
    GW --> AUTH[Authentication]
    AUTH --> POL[Tool Policy + Quotas]
    POL --> COORD[Coordinator]

    COORD --> IDX[Index Workers]
    COORD --> RET[Retrieval Workers]
    COORD --> CTX[Context Workers]

    IDX --> GRAPH[(Graph State)]
    RET --> VEC[(Persistent Vector Store)]
    CTX --> MEM[(Synchronized Team Memory)]

    COORD --> AUDIT[(Audit + Performance History)]
Workers advertise capabilities. Work is leased. Expired work can be requeued. Remote operation adds authentication, TLS support, quotas, tool policy, organization/workspace policy, and audit evidence.
The dashboard is an observability surface, not an authorization boundary.
Observatory
The local observatory can surface:
A context engine should be able to explain its own routing, evidence sources, and failure states.
Security model
Security badges are evidence, not a proof that every deployment is secure. A deployment-specific threat model still matters.
Quality, release, and benchmark doctrine
A credential-gated integration that cannot run is reported as skipped. It is not counted as success.
Benchmark command:
A public performance claim should map to a reproducible spec, pinned revision, environment, measured result, and artifact. CodeCortex does not invent token savings, speedups, task-success gains, or accuracy percentages.
Evidence Fusion Layer
Status: shipped. Implementation, tests, benchmarks, documentation, and provenance records are in the repository. All three layers are optional: CodeCortex Core runs with none of them installed and no network access.
CodeCortex fuses several kinds of evidence and tells the agent, for every result, how that result was established. Each record carries a categorical trust tier — exact, near_exact, structural, inferred_high, inferred, weak — plus a provenance label. Two properties are enforced in code, not merely documented: evidence cannot claim the exact tier unless it is fresh, and stale exact evidence never outranks fresh structural evidence.
See docs/EVIDENCE_FUSION.md for the full model, fallback behavior, and security boundaries.
1 — Precision Code Intelligence
The Precision Code Intelligence layer consumes compiler/indexer-grade occurrence evidence when available and distinguishes:
Current capabilities:
- precise definition lookup;
- precise references;
- implementation relationships;
- symbol occurrences;
- stale-index detection;
- graph fusion with exact/inferred provenance;
- graceful fallback to current intelligence.
flowchart TB
    EX[Exact index/compiler evidence] --> F[Evidence Fusion]
    SEM[Language-aware semantic evidence] --> F
    AST[AST / structural evidence] --> F
    GR[Graph inference] --> F
    HEU[Heuristic resolution] --> F
    LEX[Lexical match] --> F
    F --> CTX[Task-ranked context]
The engine should know not only what it found, but how strongly it knows it.
2 — Version-Aware Dependency Intelligence
The Dependency Intelligence layer joins:
Questions this layer answers:
- Which version is actually resolved?
- Is the requested API valid for that version?
- Is the current pattern outdated?
- Which migration guidance applies?
- Which local files and symbols use the dependency?
External documentation remains optional, minimal-data, credential-aware, cached, and explicit. Core repository intelligence must continue to work offline. Repository source should not leave the system by default just to answer a dependency question.
3 — Structural Search & Guarded Rewrite
The Structural Search & Guarded Rewrite layer handles syntax-aware patterns:
Mutation lifecycle:
flowchart LR
    Q[Migration request] --> S[Structural search]
    S --> M[Match set]
    M --> I[Impact analysis]
    I --> P[Rewrite preview]
    P --> A{Mutation allowed?}
    A -- No --> STOP[Preview only]
    A -- Yes --> W[Bounded rewrite]
    W --> R[Reindex]
    R --> V[Validation]
    V --> POST[Post-change impact]
A rewrite should be previewed, bounded, content-hash checked, policy-authorized, reindexed, and validated.
Evidence fusion in practice
Example, covered end to end by an acceptance test:
Migrate authentication middleware to the supported API for the version used by this repository.
Stream:
The value is not three disconnected tools. The value is one context engine joining local code truth, precise relationships, dependency-version evidence, structural patterns, history, and validation for one task.
Measured on fixture repositories (cortex evidence-benchmark; strategies that cannot be measured are reported as skipped, never estimated):
Shipped capabilities and fallback behavior
Operating profiles
What CodeCortex is not
Design rules
- Typed boundaries.
- Replaceable intelligence.
- Local operation first.
- Explicit context budgets.
- Project-scoped state by default.
- Provenance survives summarization.
- Mutation is a separate privilege.
- Distributed state is explicit.
- Missing evidence stays missing.
- Release claims map to evidence.
Command map
Docker
Containerization does not replace authentication, TLS, policy, secret management, or an appropriate deployment threat model.
Project status
CodeCortex is currently alpha.
Public interfaces are still evolving. Breaking changes can occur before 1.0. Evaluate the project by what the current code, tests, CI, documentation, and reproducible artifacts demonstrate.
Engineering use cases
Community
Good First Issues · Report a Bug · Contributing Guide
Documentation
- Architecture
- Distributed operation
- Advanced intelligence
- Evidence fusion
- Integrations
- Quality
- Testing
- Release
- Licensing
- Security
- Contributing
- Governance
- Roadmap
- Cloud & Enterprise Early Access
FAQ
Maintainer, contribution, and license
CodeCortex is built and maintained by Behnam Jalali.
CodeCortex-owned material is licensed under Apache License 2.0. Third-party material remains subject to the license and attribution records kept in the repository.
See LICENSE, NOTICE, SECURITY.md, and CONTRIBUTING.md.
CodeCortex Context Engine
Give the agent a map before asking it to navigate the codebase.
Less noise. More evidence. Inspectable change.
🇮🇷 فارسی
🧠 موتور کانتکست CodeCortex
قبل از اینکه ایجنت حدس بزند، ریپو باید بتواند خودش را توضیح بدهد.
CodeCortex در یک جمله
CodeCortex یک ریپوی نرمافزاری را به یک سیستم شواهدِ مخصوص همان سؤال تبدیل میکند تا ایجنت برنامهنویسی بهجای حدس زدن، با نقشه و مدرک جلو برود.
CodeCortex بین ایجنت و کدبیس میایستد. از ساختار ریپو، سیمبلها، رابطهها، تاریخچه Git، ownership، معماری، تصمیمهای تیم، impact و validation یک لایه هوشمندی ماندگار میسازد. بعد برای هر تسک تلاش میکند کوچکترین بسته evidence مفید را برگرداند، نه اینکه مدل را مجبور کند هر بار نصف ریپو را باز کند و همان واقعیتها را دوباره از صفر بسازد.
این پروژه یک چتبات دیگر نیست. model provider هم نیست. قرار نیست ادعا کند ایجنت را بدون خطا میکند. CodeCortex زیرساخت کانتکست است؛ یعنی چیزی که کیفیت اطلاعات ورودی به reasoning ایجنت را بهتر میکند.
قاعده اصلی: اول evidence را پیدا کن، بعد با confidence حرف بزن.
چرا اصلاً به چنین چیزی نیاز داریم؟
مدل قوی میتواند کد بخواند. مسئله سخت مهندسی این است که بداند کدام کد ارزش توجه دارد، چه چیزی به آن وصل است، چه چیزی عوض شده، کجا ambiguity داریم، مالک آن بخش کیست و اگر تغییر اشتباه باشد چه چیزی میشکند.
بدون موتور کانتکست، جریان معمولاً این شکلی میشود:
CodeCortex جریان را عوض میکند:
هدف کانتکست بیشتر نیست.
هدف evidence مفیدتر به ازای هر توکن است.
معماری سیستم
استریم زنده Evidence
flowchart LR
    A[AI Coding Agent] --> G[CodeCortex Gateway]
    G --> R[Adaptive Router]

    R --> REP[Repository Intelligence]
    R --> SYM[Symbol Intelligence]
    R --> RET[Hybrid Retrieval]
    R --> GIT[Git + PR Intelligence]
    R --> MEM[Project + Team Memory]
    R --> ARC[Architecture + Drift]
    R --> IMP[Impact + Validation]

    REP --> E[Evidence Surface]
    SYM --> E
    RET --> E
    GIT --> E
    MEM --> E
    ARC --> E
    IMP --> E

    E --> C[Context Pipeline]
    C --> B[Rank + Dedup + Slice + Budget]
    B --> G
    G --> A
حقیقت اجرایی همچنان سورس فعلی، کانفیگ و تست است. Graph، memory، semantic retrieval، architecture inference و summary برای فهم بهتر هستند؛ جای source truth را نمیگیرند.
نقشه قابلیتهای فعلی
دکترین CodeCortex
اینها slogan نیستند؛ قانون مهندسیاند.
دکترین ۰۱ — اول evidence، بعد confidence
سیمبل resolveشده، semantic match، edge استنباطی، memory و Git observation کیفیت یکسان ندارند. CodeCortex نباید همه را با یک certainty تحویل دهد.
دکترین ۰۲ — کوچکترین کانتکستِ کافی
بهترین context package بزرگترین چیزی نیست که جا شود. بهترین package کمحجمترین چیزی است که برای همان task سورس، رابطه، history و validation کافی داشته باشد.
دکترین ۰۳ — Source همچنان Source است
Memory میتواند دلیل را توضیح دهد. Git تاریخچه را. Graph رابطه را. Retrieval ارتباط احتمالی را. اما رفتار اجرایی را سورس فعلی، کانفیگ، تست و artifact قابل بازتولید مشخص میکند.
دکترین ۰۴ — ابهام خودش اطلاعات است
اگر دو سیمبل target محتملاند، این ambiguity مهم است. اگر معماری inference است، missing signal مهم است. اگر integration اختیاری در دسترس نیست، unavailable بهتر از success ساختگی است.
دکترین ۰۵ — هر تغییر Blast Radius دارد
diff کوچک میتواند پرریسک باشد و diff بزرگ میتواند مکانیکی باشد. سؤال درست این است: چه سیمبلی تغییر کرد، چه کسی به آن وابسته است، چه تستی مسیر را پوشش میدهد، مالک بخش کیست و risk بر چه evidenceای بنا شده.
دکترین ۰۶ — Local-first یک تصمیم اعتماد است
Core intelligence local کار میکند. هر network boundary، credential، remote tool، quota، policy و data transfer باید صریح باشد.
دکترین ۰۷ — Reproducibility از عدد جذاب مهمتر است
Benchmark بدون spec، revision، environment، measured output و artifact evidence قوی نیست.
دکترین ۰۸ — Scale با Coordination صریح ساخته میشود
Worker هویت، capability، lease، failure، retry و state دارد. Shared memory sync و conflict دارد. ابزار remote auth و policy دارد.
شروع سریع
نصب
CodeCortex از Python 3.11، 3.12 و 3.13 پشتیبانی میکند.
Parser اختیاری:
Embedding معنایی local اختیاری:
داخل یک ریپو شروع کن
مدل ذهنی ۳۰ ثانیهای
ایجنت هنوز خودش reasoning میکند. CodeCortex چیزی را بهتر میکند که ایجنت با آن reasoning میکند.
استریمهای Task
Bug Investigation
sequenceDiagram
    participant A as Agent
    participant C as CodeCortex
    participant R as Repository
    participant G as Graph
    participant H as Git/History
    participant V as Validation

    A->>C: Trace a failing behavior
    C->>R: locate source and symbols
    C->>G: resolve callers and dependencies
    C->>H: inspect recent change and ownership
    C->>V: identify tests and validation signals
    C-->>A: compact evidence package + impact
Investigation خوب باید جواب دهد:
- رفتار کجا پیاده شده؟
- چه caller و referenceهایی در مسیرند؟
- اخیراً چه چیزی تغییر کرده؟
- چه مسیر دیگری hypothesis را رد میکند؟
- کدام test باید fail شود اگر توضیح اشتباه است؟
- کوچکترین تغییر امن چیست؟
Pull Request Review
اندازه PR فقط یکی از signalهاست.
Multi-Repository
هویت ریپوها حفظ میشود. Evidence federate میشود، نه اینکه وانمود کنیم همه یک codebase فیزیکی هستند.
سطحهای هوشمندی
Incremental indexing فایلها و program unitها را به state ماندگار تبدیل میکند. Retrieval، معماری، impact و MCP میتوانند همان state را دوباره استفاده کنند.
Parsing زبانآگاه program unit را استخراج میکند. Cross-file resolution ambiguity و دلیل candidateها را نگه میدارد و same-name symbol را بیصدا یکی فرض نمیکند.
کد prose معمولی نیست. CodeCortex semantic similarity را با lexical evidence، metadata سیمبل و structural context ترکیب میکند و بهجای file dump، slicing محدود میدهد.
Source میگوید الان چه اتفاقی میافتد. Git میگوید چطور به اینجا رسیده. History، blame، ownership، churn و PR analysis شواهد تغییر را به مدل static اضافه میکنند.
Project memory fact و decision را نگه میدارد. Team memory revision، actor/source metadata و conflict behavior دارد. Memory «چرا» را نگه میدارد ولی از source و test معتبرتر فرض نمیشود.
Architecture inference evidence و confidence برمیگرداند. Fingerprint ذخیرهشده با graph فعلی مقایسه میشود تا dependency direction و coupling drift دیده شود.
Impact relationship معکوس و affected test را دنبال میکند. Validation تغییر پیشنهادی را مقابل evidence ریپو challenge میکند.
ویرایش کنترلشده
عملیات semantic فعلی:
دکترین تغییر:
نه:
MCP: یک سطح واحد برای ایجنت
MCP نقشه ریپو، symbol search، reference، dependency graph، impact، hybrid retrieval، compact context، architecture، Git، PR، memory، workspace، trace، validation و stats را ارائه میدهد.
عملیات توزیعشده
flowchart TB
    AG[AI Agents] --> GW[Remote MCP Gateway]
    GW --> AUTH[Authentication]
    AUTH --> POL[Tool Policy + Quotas]
    POL --> COORD[Coordinator]

    COORD --> IDX[Index Workers]
    COORD --> RET[Retrieval Workers]
    COORD --> CTX[Context Workers]

    IDX --> GRAPH[(Graph State)]
    RET --> VEC[(Persistent Vector Store)]
    CTX --> MEM[(Synchronized Team Memory)]

    COORD --> AUDIT[(Audit + Performance History)]
Worker capability اعلام میکند، work lease میشود و expired work میتواند requeue شود. Remote operation میتواند auth، TLS، quota، tool policy، organization/workspace policy و audit evidence داشته باشد.
Dashboard سطح observability است، نه authorization.
Observatory
Observatory میتواند اینها را نشان دهد:
موتور کانتکست باید بتواند routing، منبع evidence و failure state خودش را توضیح دهد.
مدل امنیت
Badge امنیتی evidence است، نه تضمین امنیت همه deploymentها. Threat model مخصوص محیط همچنان لازم است.
دکترین Quality، Release و Benchmark
Integrationای که credential ندارد باید skipped گزارش شود، نه success.
Benchmark:
Claim performance باید به spec بازتولیدپذیر، revision پینشده، environment، measured result و artifact وصل باشد. CodeCortex نباید token saving، speedup، task success یا accuracy ساختگی منتشر کند.
لایه Evidence Fusion
وضعیت: منتشر شده. implementation، test، benchmark، documentation و سوابق provenance همگی داخل ریپو هستند. هر سه لایه اختیاریاند: هسته CodeCortex بدون هیچکدام از آنها و بدون دسترسی شبکه کار میکند.
CodeCortex چند نوع evidence را با هم ترکیب میکند و برای هر نتیجه میگوید آن نتیجه چطور اثبات شده است. هر رکورد یک trust tier مشخص دارد — exact، near_exact، structural، inferred_high، inferred، weak — بههمراه برچسب provenance. دو قاعده در خودِ کد اجرا میشوند، نه فقط در مستندات: هیچ evidenceای تا وقتی تازه نباشد نمیتواند ادعای exact کند، و evidence قدیمی هرگز بالاتر از evidence ساختاری تازه رتبه نمیگیرد.
مدل کامل، رفتار fallback و مرزهای امنیتی در docs/EVIDENCE_FUSION.md آمده است.
۱ — Precision Code Intelligence
لایه Precision Code Intelligence در صورت وجود evidence دقیق compiler/indexer-grade تفاوت این سطوح را تشخیص میدهد:
قابلیتهای فعلی:
- definition دقیق؛
- reference دقیق؛
- implementation relationship؛
- occurrence سیمبل؛
- stale-index detection؛
- fusion گراف با provenance دقیق/استنباطی؛
- fallback به intelligence فعلی.
flowchart TB
    EX[Exact index/compiler evidence] --> F[Evidence Fusion]
    SEM[Language-aware semantic evidence] --> F
    AST[AST / structural evidence] --> F
    GR[Graph inference] --> F
    HEU[Heuristic resolution] --> F
    LEX[Lexical match] --> F
    F --> CTX[Task-ranked context]
سیستم باید فقط نداند چه پیدا کرده؛ باید بداند چقدر دقیق میداند.
۲ — Dependency Intelligence با آگاهی از نسخه
لایه Dependency Intelligence این اطلاعات را کنار هم قرار میدهد:
سؤالهایی که این لایه پاسخ میدهد:
- نسخه واقعی resolveشده چیست؟
- API پیشنهادی برای همین نسخه معتبر است؟
- pattern فعلی قدیمی است؟
- migration guidance مرتبط چیست؟
- کدام file و symbol از dependency استفاده میکند؟
Documentation بیرونی باید optional، minimal-data، credential-aware، cacheشده و explicit باشد. Core باید offline هم کار کند. سورس ریپو نباید برای جواب dependency question بهصورت پیشفرض از سیستم خارج شود.
۳ — Structural Search و Guarded Rewrite
لایه Structural Search و Guarded Rewrite برای patternهای syntax-aware:
جریان mutation:
flowchart LR
    Q[Migration request] --> S[Structural search]
    S --> M[Match set]
    M --> I[Impact analysis]
    I --> P[Rewrite preview]
    P --> A{Mutation allowed?}
    A -- No --> STOP[Preview only]
    A -- Yes --> W[Bounded rewrite]
    W --> R[Reindex]
    R --> V[Validation]
    V --> POST[Post-change impact]
Rewrite باید preview، bound، content-hash check، policy authorization، reindex و validation داشته باشد.
مقصد واقعی: Evidence Fusion
مثال task آینده:
Middleware احراز هویت را به API درست برای نسخهای که همین پروژه استفاده میکند migrate کن.
استریم مطلوب:
ارزش اصلی سه ابزار جدا نیست. ارزش اصلی یک context engine است که حقیقت محلی کد، رابطه دقیق، نسخه dependency، pattern ساختاری، history و validation را برای یک task به یک package تبدیل کند.
وضعیت فعلی و رفتار fallback
پروفایلهای استفاده
CodeCortex چه چیزی نیست؟
قوانین طراحی
- Boundary typed.
- Intelligence قابل تعویض.
- Local-first.
- Context budget صریح.
- State پروژهای بهصورت پیشفرض.
- Provenance بعد از summary هم باقی میماند.
- Mutation privilege جداست.
- Distributed state صریح است.
- Evidence گمشده ساخته نمیشود.
- Claim انتشار evidence میخواهد.
نقشه دستورات
Docker
Containerization جای auth، TLS، policy، secret management و threat model مناسب را نمیگیرد.
وضعیت پروژه
CodeCortex فعلاً Alpha است.
interfaceهای عمومی هنوز تکامل پیدا میکنند و قبل از 1.0 breaking change ممکن است. پروژه را باید با چیزی سنجید که code، test، CI، documentation و artifact قابل بازتولید واقعاً نشان میدهند.
سناریوهای مهندسی
مشارکت در پروژه
Good First Issues · گزارش باگ · راهنمای مشارکت
مستندات
- Architecture
- Distributed
- Advanced Intelligence
- Evidence Fusion
- Integrations
- Quality
- Testing
- Release
- Licensing
- Security
- Contributing
- Governance
- Roadmap
- Cloud & Enterprise Early Access
سؤالهای پرتکرار
نگهداری، مشارکت و License
CodeCortex توسط Behnam Jalali ساخته و نگهداری میشود.
بخشهای متعلق به CodeCortex تحت Apache License 2.0 منتشر میشوند. اجزای ثالث تابع license و attribution ثبتشده در خود ریپو هستند.
فایلهای LICENSE، NOTICE، SECURITY.md و CONTRIBUTING.md را ببینید.
CodeCortex Context Engine
قبل از اینکه از ایجنت بخواهی داخل کدبیس حرکت کند، به آن نقشه بده.
نویز کمتر. Evidence بیشتر. تغییر قابل بررسی.